Gemini 3.1 Flash-Lite 发布:$0.25/$1.50 每百万 token,Arena.ai Elo 1432、GPQA Diamond 86.9%
Gemini 3.1 Flash-Lite: Built for intelligence at scale
精选评分 65

导读
Google DeepMind 发布 Gemini 3.1 Flash-Lite,称其为 Gemini 3 系列里最快、最具成本效益的型号,面向大规模高并发的开发者负载,已在 Gemini API(Google AI Studio)开放预览、企业侧走 Vertex AI。口径很实:定价每百万输入 token 0.25 美元、输出 1.50 美元;按 Artificial Analysis 基准,较 2.5 Flash 首 token 响应快 2.5 倍、输出速度高 45%,质量持平或更好;Arena.ai 榜 Elo 1432,GPQA Diamond 86.9%、MMMU Pro 76.8%。
推荐理由
单价、速度对比与基准分数一次给全,批量推理选型可直接算账。
主体与标签
Google#模型发布#定价/成本#评测/基准
正文
Get best-in-class intelligence for your highest-volume workloads.
Your browser does not support the audio element.
This content is generated by Google AI. Generative AI is experimental
Today, we're introducing Gemini 3.1 Flash-Lite, our fastest and most cost-efficient Gemini 3 series model. Built for high-volume developer workloads at scale, 3.1 Flash-Lite delivers high quality for its price and model tier.
Starting today, 3.1 Flash-Lite is rolling out in preview to developers via the Gemini API in Google AI Studio and for enterprises via Vertex AI .
Cost-efficiency without compromise
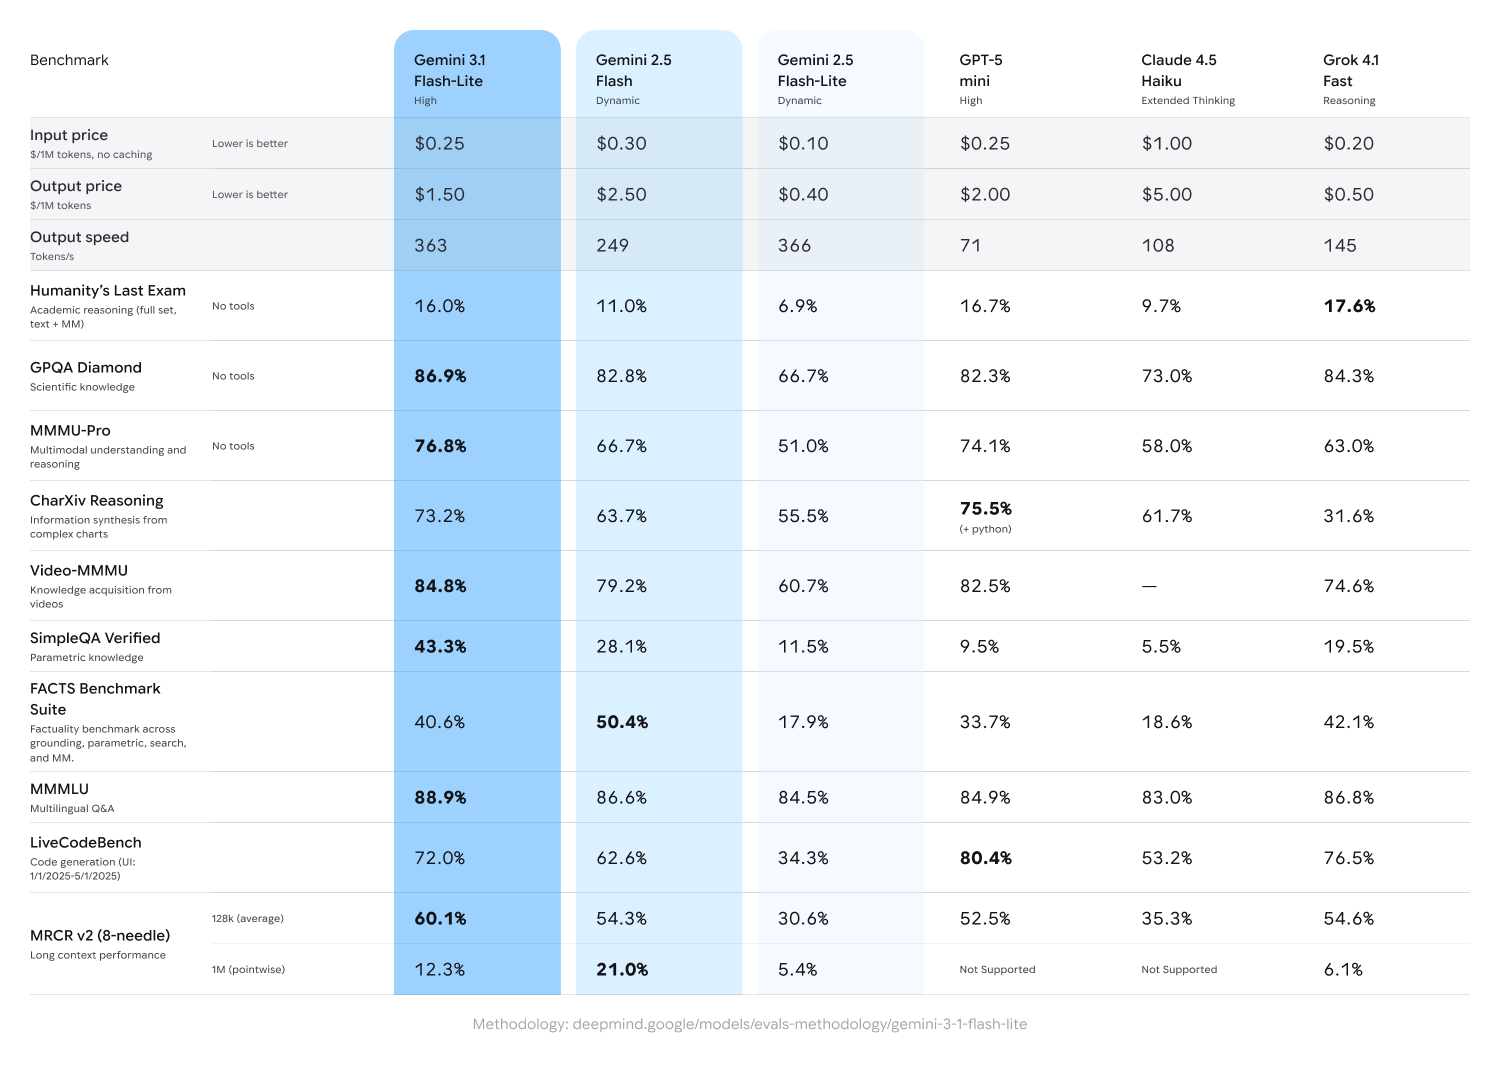
Priced at just $0.25/1M input tokens and $1.50/1M output tokens, 3.1 Flash-Lite delivers enhanced performance at a fraction of the cost of larger models. It outperforms 2.5 Flash with a 2.5X faster Time to First Answer Token and 45% increase in output speed, according to the Artificial Analysis benchmark while maintaining similar or better quality. This low latency is needed for high-frequency workflows, making it an ideal model for developers to build responsive, real-time experiences.

Gemini 3.1 Flash-Lite outperforms 2.5 Flash in speed and quality.
3.1 Flash-Lite achieves an impressive Elo score of 1432 on the Arena.ai Leaderboard and outperforms other models of similar tier across reasoning and multimodal understanding benchmarks, including 86.9% on GPQA Diamond and 76.8% on MMMU Pro–even surpassing larger Gemini models from prior generations like 2.5 Flash.
Adaptive intelligence at scale for developers
Beyond its raw performance, Gemini 3.1 Flash-Lite comes standard with thinking levels in AI Studio and Vertex AI, giving developers the control and flexibility to select how much the model “thinks” for a task, which is critical for managing high-frequency workloads. 3.1 Flash-Lite can tackle tasks at scale, like high-volume translation and content moderation, where cost is a priority. And it can also handle more complex workloads where more in-depth reasoning is needed, like generating user interfaces and dashboards, creating simulations or following instructions.
Early-access developers on AI Studio and Vertex AI, and companies like Latitude, Cartwheel and Whering are already using 3.1 Flash-Lite to solve complex problems at scale. Early testers highlighted 3.1 Flash-Lite’s efficiency and reasoning capabilities, saying it can handle complex inputs with the precision of a larger-tier model, plus follow instructions and maintain adherence.
We look forward to seeing what you build with 3.1 Flash-Lite and the rest of the Gemini 3 series models.