GitHub 推出 Project HydraFusion(研究预览):一次任务、多个模型接力——运行时自动编排跨供应商的起草-批判-修订与向更强模型级联
Project HydraFusion: Frontier quality via multi-model orchestration
评分 49
导读
GitHub 博客:"给开发者手头任务配最好的模型"一直是目标,此前上线的 Auto model selection 按任务匹配单模型;今天的 Project HydraFusion 研究预览更进一步:由运行时编排交付前沿质量——为任务制定完整执行计划,跨多个供应商的模型选择谁来起草、批判与修订,必要时级联到更强模型收尾。GitHub 把它定位为"本地/云端/复合模型间自动化语义路由"总体策略的一环。
主体与标签
GitHub#产品更新#推理#开发者工具#多模型
正文
Providing developers the best model for the task at hand has always been our goal. Earlier this year, we made that easier by launching Auto model selection, which reviews your task and matches it to the best-suited model for that task.
Today, we’re introducing Project HydraFusion, a research preview that delivers frontier intelligence through runtime orchestration. It creates a full execution plan, choosing from models across multiple providers to draft, critique and revise, or cascade to more powerful models to complete your task.
HydraFusion fills a key role in our overall strategy to deliver automated semantic routing between local, cloud, and compound models. For developers, that complexity stays behind the scenes: you select HydraFusion like any other model, and it chooses a workflow that balances performance, cost, and latency for each task.
Now available as a research preview
HydraFusion is available to users on all GitHub Copilot plans through /experimental in GitHub Copilot CLI . Usage is based on the tokens consumed by the models HydraFusion uses, priced at each model’s standard rate .
To try HydraFusion in Copilot CLI:
- Run /update to install the latest version
- Run /experimental on
- Run /model , then select HydraFusion (Research Preview)
Please post feedback in the GitHub Community .
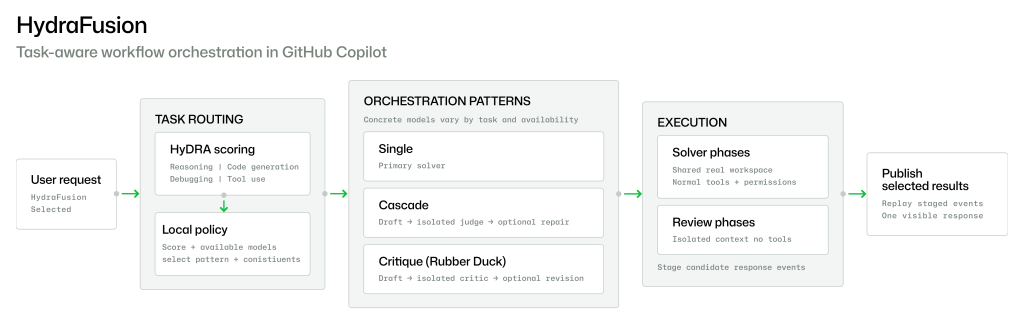
HydraFusion treats workflow selection as an optimization problem. It uses capability signals for reasoning, code generation, debugging, and tool use to select the most efficient execution pattern to meet the quality bar.
For each request, HydraFusion currently chooses one of three execution patterns:
- Single. One selected model solves the task directly.
- Cascade. An efficient model drafts a solution and a quality gate decides whether to accept it or escalate to a stronger model.
- Critique. One model drafts a result, an independent read-only critic from a different model family reviews it (following the same review pattern as Rubber Duck ), and the drafting model revises once.
Each pattern addresses a different quality-to-cost trade-off. Single preserves speed and efficiency when one model can solve the task directly. Cascade gives an efficient model the first attempt while retaining a path to stronger inference when the candidate does not clear the acceptance gate. Critique adds an independent perspective for tasks where review is more useful than another unaided attempt.
In offline evaluations across three agentic coding benchmarks, HydraFusion consistently demonstrated frontier-level quality with substantial estimated cost savings. On TerminalBench 2.1, it improved verified task quality by 4.9 percentage points at 67% lower estimated cost compared with Claude Opus 5.
Let’s dive into the approach, the results, and the benchmarks.
Adaptive multi-model orchestration
Developers already coordinate models manually: choosing one for a task, asking another to review the work, or escalating a difficult problem to a more capable model. HydraFusion brings that familiar process into the runtime. You choose HydraFusion once and stay focused on your task while it manages the models and workflow behind the scenes.
The key is selectivity. Some coding tasks can be solved directly, while others benefit from review, revision, or escalation. HydraFusion evaluates each request and chooses the least complex workflow expected to meet its needs, using additional model calls only when they are likely to improve the result. This adaptive approach balances quality, cost, and latency across models.
As the model frontier advances, so does HydraFusion. When new models become available in GitHub Copilot, we can evaluate and incorporate them into its model pool, bringing their strengths to the tasks best suited to them.
Building HydraFusion
Turning adaptive multi-model orchestration into one dependable coding experience requires careful control of execution, review, cost, and repository state. HydraFusion is built around five operating principles:
- Complete accounting. Aggregate cost and usage across every workflow leg, including drafting, critique, revision, escalation, retry, and fallback.
- Bounded execution. Give each leg explicit timeout and cancellation behavior to keep execution and cost within defined limits.
- Isolated review. Run review steps in isolated, tool-less contexts, while solver steps use the shared workspace and normal permission-aware agent loop. This allows models to assess the work independently without modifying the repository.
- Fail-safe application. Apply no patch when the workflow is cancelled or fails validation, preventing incomplete changes from reaching the repository.
- Validated routing. Verify workflow definitions, model bindings, fallback behavior, and model availability before execution begins.
Together, these principles make multi-model orchestration practical for repository-level work. Internally, the runtime records the role, outcome, cost, latency, and diagnostics of each leg so the workflow can be understood after execution. Externally, the developer receives one coherent response and one permission-aware change set.
Showing progress without showing unfinished work
- Today: HydraFusion shows workflow stages but holds intermediate drafts until it returns one coherent result.
- Why: Those drafts may be reviewed, revised, or discarded, so showing them live could make unfinished work appear final.
- What we’re learning: Waiting without enough visibility is a real trade-off for developers.
- Next: We’re actively exploring better progress updates, guided by feedback from the research preview.
Benchmarking results
Fixed HydraFusion policies were evaluated across three agentic coding benchmarks — TerminalBench 2.1, DeepSWE, and CheckpointBench, our internal benchmark based on real GitHub Copilot sessions — using Claude Opus 5 and GPT-5.6 Sol as comparison baselines. Each policy used the same task inputs, tools, execution limits, pricing assumptions, grading conditions, and treatment of missing results. The evaluation measured verified task quality, which is the share of tasks confirmed as correctly answered, and the complete estimated workflow cost. Cost accounting included every invoked leg, such as drafting, critique, revision, escalation, retry, and fallback. The results below show the best tuned HydraFusion configuration.
| Benchmarks | Cost vs. Opus 5 | Quality vs. Opus 5 |
| TerminalBench 2.1 | 67% lower | +4.9 points |
| DeepSWE | 36% lower | -1.5 points |
| CheckpointBench | 65% lower | -0.1 points |
These controlled offline results are specific to the evaluated benchmark revisions, workflow configurations, model pool, and pricing assumptions, with all models evaluated at the same medium reasoning level. Through this research preview, we’ll validate how these results translate to real developer workloads and use the findings to further optimize HydraFusion for production quality, latency, reliability, caching efficiency, cost, and safety.
TerminalBench 2.1
TerminalBench 2.1 evaluates coding agents on complex, multi-step tasks in terminal environments.
Figure 2 compares HydraFusion and Opus 5 across verified task quality and estimated workflow cost.
DeepSWE
DeepSWE evaluates challenging repository-level software engineering tasks that require navigating large codebases, understanding cross-file dependencies, and producing end-to-end fixes. On this benchmark, HydraFusion comes within 1.5 percentage points of Opus 5 while reducing cost by 36%, demonstrating a compelling quality-cost tradeoff for complex real-world engineering tasks.
CheckpointBench
CheckpointBench is an internal multi-turn benchmark curated from real GitHub Copilot agentic coding sessions. Each conversation is anchored to a specific public repository and immutable commit, ensuring every session is replayable. The benchmark is balanced across language, task type, difficulty, scrubbed for quality, resulting in a realistic evaluation set that closely mirrors production agentic sessions. On this benchmark, HydraFusion comes within 0.1 percentage points of Opus 5 at 65% lower cost.
Early internal testing has echoed that result.
So far, the reasoning and task solving capability [of HydraFusion] is at or better than Opus. Principal Software Engineer at Microsoft
Hill-climbing HydraFusion
HydraFusion’s routing policies were shaped by how developers use GitHub Copilot on real coding tasks. To make those workflows reproducible, we curated CheckpointBench from real Copilot coding-session trajectories. We refined HydraFusion repeatedly across CheckpointBench, DeepSWE, and TerminalBench 2.1, optimizing across the evaluation sets rather than for any single benchmark.
HydraFusion’s per-capability scores provided a consistent basis for comparing candidate routing policies. Instead of manually tuning thresholds, we used beam search to build the optimal decision policy. Each candidate was measured against a frozen baseline on quality, cost, and failure modes, so improvements were evaluated on stable ground.
TerminalBench 2.1 provides the most complete sequence of runs, making it the clearest view of this iterative improvement. The progression was not linear. Between August 11 and August 25, two operational failures in the evaluation harness produced invalid runs. Those failures were excluded from the performance trend, corrected, and followed by continued gains in the HydraFusion configurations. By August 25, HydraFusion had reached its strongest operating points in the recorded series.